Sunday, December 6, 2009

The Real Ajay Bhatt of Intel's 2009 Ad Campaign

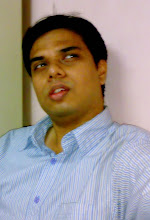
Here's the picture of Real Ajay Bhatt


You must have seen this Intel's ad on your television many times, here's what you don't know about this ad.
The tagline of the advertisement is ''our rock stars are different from your rock stars.'' The ad is great but the only person missing in the ad is the Real Ajay Bhatt. Yes, the ad is played by some actor instead of Real Ajay Bhatt.

Ajay V. Bhatt is an Indian-American computer architect. He has been instrumental in driving definition and development of broadly adopted technologies such as USB (Universal Serial Bus), AGP (Accelerated Graphics Port), PCI Express, Platform Power management architecture and various chipset enhancements. Ajay Bhatt rose to global celebrity as the co-inventor of USB through an Intel 2009 TV advertisement, where he was portrayed by actor Sunil Narkar.
The ad was created by the agency Venables Bell & Partners.
After completing his graduation from the Maharaja Sayajirao University of Baroda, India, Bhatt received his master's degree from The City University of New York. Ajay Bhatt is an Intel Fellow and Chief Client Platform Architect for the Intel Architecture Group at Intel Corporation. Bhatt leads definition and development of the next-generation Client Platform architecture. He is primarily focused on the novel advances in platform hardware and software by working with key internal and external technology partners to develop the future Client Platform Architectures and Technologies. As a lead Client Platform Architect, Ajay also works with key business and planning groups to be at the forefront of the future Client Platform innovation areas by setting Intel-wide and industry-impacting strategies.
In addition, Bhatt continues to hold a position of Intel's Chief I/O architect. In his role as a Chief I/O architect, he is responsible for the platform and I/O interconnects directions for Intel; leading the definition of next-generation platform architectures and I/O technologies across the market segments internally and within the industry.
Bhatt is an industry-recognized expert in the area of I/O technologies. At Intel, Bhatt has been instrumental in driving definition and development of broadly adopted technologies such as USB, Accelerated Graphics Port, PCI Express, Platform Power management architecture and various chipset enhancements. Bhatt joined Intel in 1990 as a senior staff architect on the chipset architecture team in Folsom.
Bhatt received his master's degree from The City University of New York. He holds nine U.S. patents with several in various stages of filing. In 1998, 2003 and 2004 Bhatt was nominated to take part in a Distinguished Lecture Series at leading universities in the United States and Asia. He received an Achievement in Excellence Award for his contribution in PCI Express specification development in 2002.

Friday, December 4, 2009

Log4j MDC (Mapped Diagnostic Context) : What and Why

I hope that Log4j does not need any introduction and I assume that you already have basic understanding of Log4j. If not, I’ll recommend you to first read read my previous post to get an understanding.


That said, now I’ll start with MDC or Mapped Diagnostic Context. Don’t get scared with this name! MDC is not that tough. It’s a simple yet useful concept. Before I explain what is MDC, lets assume that we are going to develop a simple web application with one servlet ‘MyServlet’ servicing requests from multiple clients. And, this servlet uses log4j framework for logging. A file appender has been defined for this servlet, so all the log messages will be logged into a text file.

With the above said configuration, all the log messages from MyServlet will go into a single log file. And when this servlet is serving more than one clients at the same time, the log statements will be mixed and there’s no way to differentiate which log statement is belongs to which client’s processing. This’ll make it difficult to trace and debug if any processing error occured in MyServlet life cycle.

How to differentiate log statements with respective to each clients?:-
To avoid the log statements mix-in, we could add a user name (or some other data which will be unique to each client) to our log statements. To do this, we have to make sure that we pass this user name data explicitley to each and every log statements, which is a tedious and repetitive work. But, no need to worry! Log4j has an excellent way to overcome this. It’s called as MDC or Mapped Diagnostic Context.

So, What is Log4j MDC (Mapped Diagnostic Context):-
To put is simple, the MDC is a map which stores the context data of the particular thread where the context is running. To explain it, come back to our simple application – every client request will be served by different thread of the MyServlet. So, if you use log4j for logging, then each thread can have it’s own MDC which is global to the entire thread. Any code which is part of that thread can easily access the values that are present in thread’s MDC.


So, how do we make MDC to differentiate logging statements from multiple clients? Simple : Before starting any business process in your code, get the user name (for our Servlet, we can get it from request object) and put that into MDC. Now the user name will be available to the further processing. In your log4j.properties while defining the ‘conversionPattern’, add a pattern %X{key} to retrievce the values that are present in the MDC. The key will be ‘userName’ in our example. It’s like getting a value from a Session object.

In my next post, I’ll give the source code for the same example that I used in this post. So, keep Watching!

Thursday, December 3, 2009

Log4j Tutorial : Adding Log4j logging to your project

If you are new to Log4j, here is a short description on what is it and why should we care about it:
Log4j is a flexible logging library, an open source project from Apache. Using Log4j, we can replace the debugging print line statements, like System.out.println(”Value is ” + someVariable), with a configurable logging statement like logger.debug(”Value is ” + someVariable). The advantage in using Log4j is, if you do not want to print the debugging print lines in production application, you can easily switch them off using Log4j configuration file (which we will see it how, shortly).
How to add Log4j support to your project?
Follow these steps if you want to add Log4j logging support to your Java project.
Download the latest Log4j distribution from Apache website (at the time of this article is written, the latest version of Log4j is 1.2) and put the log4j-xxx.jar in your project class path. For Java web application, you can place the jar file in WEB-INF/lib folder. For Java applications, you can place the jar in any folder, but remember to add the folder to your classpath.
Next we need to configure the Log4j library to our requirements. Log4j reads its configurations from log4j.properties file (or log4j.xml) placed in the CLASSPATH. Every log4j.properties file defines the following three things, mainly:
an Appender – this is the class file which does the actual logging. It could be a simple Console appender which dumps the log messages to stdout (screen) or a file appender, which sends the log messages to a log file.
a Layout – is nothing but how the log message is formatted. This format is very simlar to C languages’s printf function formatting.
and a Logger – a logger ties the appender with the log messages that are coming from the Java application. Basically, a logger tells that the log messages from these packages should go to some appender which will log the message in the defined layout.
Below is a sample log4j.properties for configuring the console appender for your project.


#define the console appender
log4j.appender.consoleAppender = org.apache.log4j.ConsoleAppender

# now define the layout for the appender
log4j.appender.consoleAppender.layout =
org.apache.log4j.PatternLayout
log4j.appender.consoleAppender.layout.ConversionPattern=%-4r [%t] %-5p %c %x - %m%n

# now map our console appender as a root logger, means all log messages will go to this appender
log4j.rootLogger = DEBUG, consoleAppender

In the above properties file, we are first defining a Console appender and a layout pattern (refer this complete documentation to know what’s the weired symbols in the conversion patterns means). Then we are mapping all the DEBUG level log messages from the entire application to go into the consoleAppender, since we added the consoleAppender to the rootLogger.

In any of your Java file, add the below lines, in order to start logging:

private static Logger logger = Logger.getLogger(Myclassname.class);
logger.debug("this is a sample log message.");

Now you are done. Run your application and you should be seeing the log messages coming in your console window.

Monday, November 30, 2009

Finding files in java archives by their content

While doing a bug hunting i needed to find a file containing a certain string and did not know where to look for it. At one stage of "file hunting" i needed to be able to search for the file in jars (Java Archives). Thus in searching for it i came up with a shell script using my good old friend venkys help
#!/bin/sh
2 echo Params: "$#" - \("$1"\) \("$2"\) \("$3"\) \("$4"\)
3 if test "$#" -ne 4
4 then
5 echo "Command takes exactly 4 params - Jar_name_pattern search_location file_name_pattern search_string
6 Use - for Jar_name_pattern to search for within all jars.
7 Use - for search_file_name to find with file_name_pattern only and avoid content search"
8 exit 1
9 fi
10
11 if test "$1" = "-"
12 then
13 jar_param="*.jar"
14 else
15 jar_param="$1"
16 fi
17 if test "$4" = "-"
18 then
19 search_content=1
20 else
21 search_content=0
22 fi
23 echo Executing: find "$2" -name "$jar_param"
24 file_list=`find "$2" -name "$jar_param"`
25 current_dir=`pwd`
26 cd /tmp/
27 mkdir search_file rw_not=1
28 if test -n "$rw_not"
29 then
30 echo "/tmp/ is not writeable by current user thus can search file content and exiting"
31 exit 1
32 fi
33 cd search_file
34 echo "Search Result:"
35 for jar_file in $file_list
36 do
37 inner_file_list=`jar tf "$jar_file" grep "$3"`
38 if test "$search_content" = "0"
39 then
40 if test -n "$inner_file_list"
41 then
42 jar xf "$jar_file" $inner_file_list
43 for inner_file in $inner_file_list
44 do
45 has_content=`cat $inner_file grep "$4"`
46 if test -n "$has_content"
47 then
48 echo Found in "$inner_file" @ "$jar_file"
49 fi
50 done
51 rm -rf *
52 fi
53 else
54 test -n "$inner_file_list" && echo "$jar_file"
55 fi
56 done
57 cd ..
58 rm -rf ./search_file
59 cd "$current_dir"
using this script not only can we find jars containing certain filename but also search file content to get results. Lets take three use cases - "I want to find jars that contain .properties file", "I want to find jars containing .properties file containing the word com.smartitengineering" and "I want to find jars, whose name has smart, containing .properties file containing the word com.smartitengineering". Using the script all these use cases can be achieved by using the following commands respectively:
./search-jar.sh - /home/user/ .properties -
./search-jar.sh - /home/user/ .properties com.smartitengineering
./search-jar.sh *smart*.jar /home/user/ .properties com.smartitengineering
The command takes exactly 4 arguments - jar_filename_pattern, search_dir_path, search_file_name and content_to_search. If jar_filename is "-" than it will search within all jars within search_dir_path. If content_to_search is "-" it will not search for content, but rather jars with certain filename.
As the script is in open domain I would appreciate if users would make their own edit and submit or request for features through this post's comments.

Stickies on Ubuntu

It seems that Wine is an excellent tool to run Windows application on Ubuntu. Recently I had to use Stickies and tried it on Ubuntu. So first I had to install Ubuntu. I executed the following commands to install Wine on Ubuntu 7.04 Fiesty

sudo wget http://wine.budgetdedicated.com/apt/sources.list.d/feisty.list -O /etc/apt/sources.list.d/winehq.list

sudo apt-get update

sudo apt-get install wine

For other platforms you can have a look at http://www.winehq.org/site/download. Then you have to simply download the stickies.exe and then execute

wine {PATH-TO-STICKIES}/stickies.exe

But hold on the installation is not done, you need get the following the installation steps mentioned in
http://appdb.winehq.org/appview.php?iVersionId=5169&iTestingId=4356

scroll down to Install Note and follow that. The only change will be installing the MSI file, instead of the one mentioned there use the following to install the MSI file

wine msiexec /i/{PATH-TO-MSI}MSISetup.MSI

Now try to execute

wine /.wine/{PATH-TO-STICKIES-INSTALLATION}/stickies.exe

It might say that MFC42.dll is missing, if it says so please get it from a Windows installation and copy it to /.wine/drive_c/windows/system32/ and try to execute it again

Hopefully that will be enough for Stickies Installation :).Now to get the Stickies running you can execute the following command:

sudo wine ~/.wine/drive_c/Program\ Files/stickies/stickies.exe > {PATH-TO-LOG}
2>&1 &
Though this is for Ubuntu but I guess excepting the installation procedure rest should be same across Linux platform. Let me know if any further changes were required.

Killing a process in linux

As a software enthusiast one thing I have to do several times is killing a process, some people will term it as ugly or bad, but general software developers often come across situation where killing a process is handy or necessary. I will mention some use cases later in the blog.Killing a process usually involves 2 steps. Finding the process ID that is intended to be terminated and terminating it with a kill statement. Step one for general users (like myself) again involves a ps command with some grepping and then manual lookup. I have to do these almost every time I kill a process. I have simply put this steps into the following script so that I can do them in a single command.
#!/bin/bash
if [ -z $3 ]; then
USER_STR=`whoami`
else
USER_STR=$3
fi
echo User: $USER_STR
process_str=`ps -eopid,user,cmd grep $USER_STR grep $1 grep $2`
pid=`echo $process_str cut -d' ' -f0-1`
if [ -z $pid ]; then
pid=`echo $process_str cut -d' ' -f1-2`
if [ -z $pid ]; then
pid=`echo $process_str cut -d' ' -f2-3`
if [ -z $pid ]; then
pid=`echo $process_str cut -d' ' -f3-4`
else
echo "Retrieved PID: " $pid
fi
else
echo "Retrieved PID: " $pid
fi
else
echo "Retrieved PID: " $pid
fi
if [ -z $pid ]; then
echo 'Could not execute kill. PID: ' $pid
else
kill -9 $pid
fi

If someone has any improvements please inform me about it.The shell script expects 3 arguments, of which 2 are mandatory and 1 is optional. The first 2 are grep params to identify the process. For example, to identify a Tomcat running Escenic Content Engine I use java and escenic.root to identify the process. The third param is the user to search it with. If it is not provided then whoami will be used to determine the user executing the shell.This shell script has enabled me to sync, build, deploy my projects all with a single command and this helps me save some sustainable amount of time. Now without a build server I can still achieve what a build server like Hudson can do. Actually I use this script from within Hudson and thus I almost "never" have to be concerned about deploying applications to my demo server. I hope this is useful to all

SIP application structure


As mentioned in my previous blog I feel that SIP applications are the next generation of applications for Desktop, Web and Mobile. By the will of Almighty, today I will be discussing the structure of SIP applications.We will see the main layers of the application and discuss them in bottom up approach. Any SIP application will contain 3 layers. Topmost is the Application Layer - where all the logics of the application resides and which takes care of the SIP packets. Then comes SIP Stack it self, which is responsible for abstracting the SIP packets from the application developer by providing an API to do the low level SIP stuffs. Lastly comes the Transport layer that is responsible for carrying the SIP packets and sending them to the intended destination; the SIP stack is very closely binded with this layer as it will provide transport for common protocols and developers has to extends the transport API to add more transport layer protocols.Almost any transport layer protocol can be used with SIP as long as the SIP stack recognizes it. The most commonly used transport layer protocol is UDP; on some occasions TCP and TLS are also used. We all know that all networks are converging towards IP backbone and as those protocols are IP based it should be more convenient for developers in future as they will not have to write SIP transport layers for different protocols. One challenge would be from Cell Phone to BTS; so SIP stack providers for Cell phone will have to implement transport layer for GSM and CDMA phones.IMHO the most important layer of the application structure is SIP stack. This will abstract the SIP packets and Transport layer hassles from the developers and will provide them API's to call and use them to make an SIP application. There are quite a few SIP stacks available such as reSIProcate, Jain SIP (JSR-32) and SIP Servlet (JSR-000116). Among them SIP Servlet Application (archives with sar extensions) is usually deployed in Java EE Container (BEA Weblogic, IBM Websphere, GlassFish-SailFin) or SIP Container implementing SIP Servlet. Personally I have used Jain SIP and its simplicity in usage and good API structure has created liking in me for it. In my blogs related to SIP I will be using this stack to develop examples. I will also discuss about SailFin.Application layer is where everybody gets to exercise their innovations. Now is the time to generates SIP centric ideas and implementing them. All SIP application can be categorized in four categories -
Registrar Server - A server responsible to register a SIP user and its location
Proxy Server - A server responsible to act as the main server where as it is nothing but a proxy and knows which is the real server
Redirect Server - A server that redirects request to another server; an example of this functionality would be load balancing of requests
User Agent - This is a client side entity responsible for communicating with the server and server the Client's request. Anything could be user agent such as PC Software, Cell Phone, Refrigerator, Television, Microwave Owen etc.Developers can develop applications that serve any of these purposes.By the will of Almighty, I will soon make some postings about what could be SIP applications